+ English · 简体中文 +
+ + Whisper is a general-purpose speech recognition model. It is trained on a large dataset of diverse audio and is also a multitasking model that can perform multilingual speech recognition, speech translation, and language identification. diff --git a/README.zh.md b/README.zh.md new file mode 100644 index 000000000..dc9bfe7d7 --- /dev/null +++ b/README.zh.md @@ -0,0 +1,168 @@ +# Whisper + +[[博客 (Blog)]](https://openai.com/blog/whisper) +[[论文 (Paper)]](https://arxiv.org/abs/2212.04356) +[[模型卡片 (Model card)]](https://github.com/openai/whisper/blob/main/model-card.md) +[[Colab 示例]](https://colab.research.google.com/github/openai/whisper/blob/master/notebooks/LibriSpeech.ipynb) + ++ English · 简体中文 +
+ +Whisper 是一个通用的语音识别(ASR)模型。它在包含多样化音频的大规模数据集上训练而成,同时也是一个多任务模型,能够执行多语言语音识别、语音翻译以及语种识别。 + + +## 架构与方法 (Approach) + +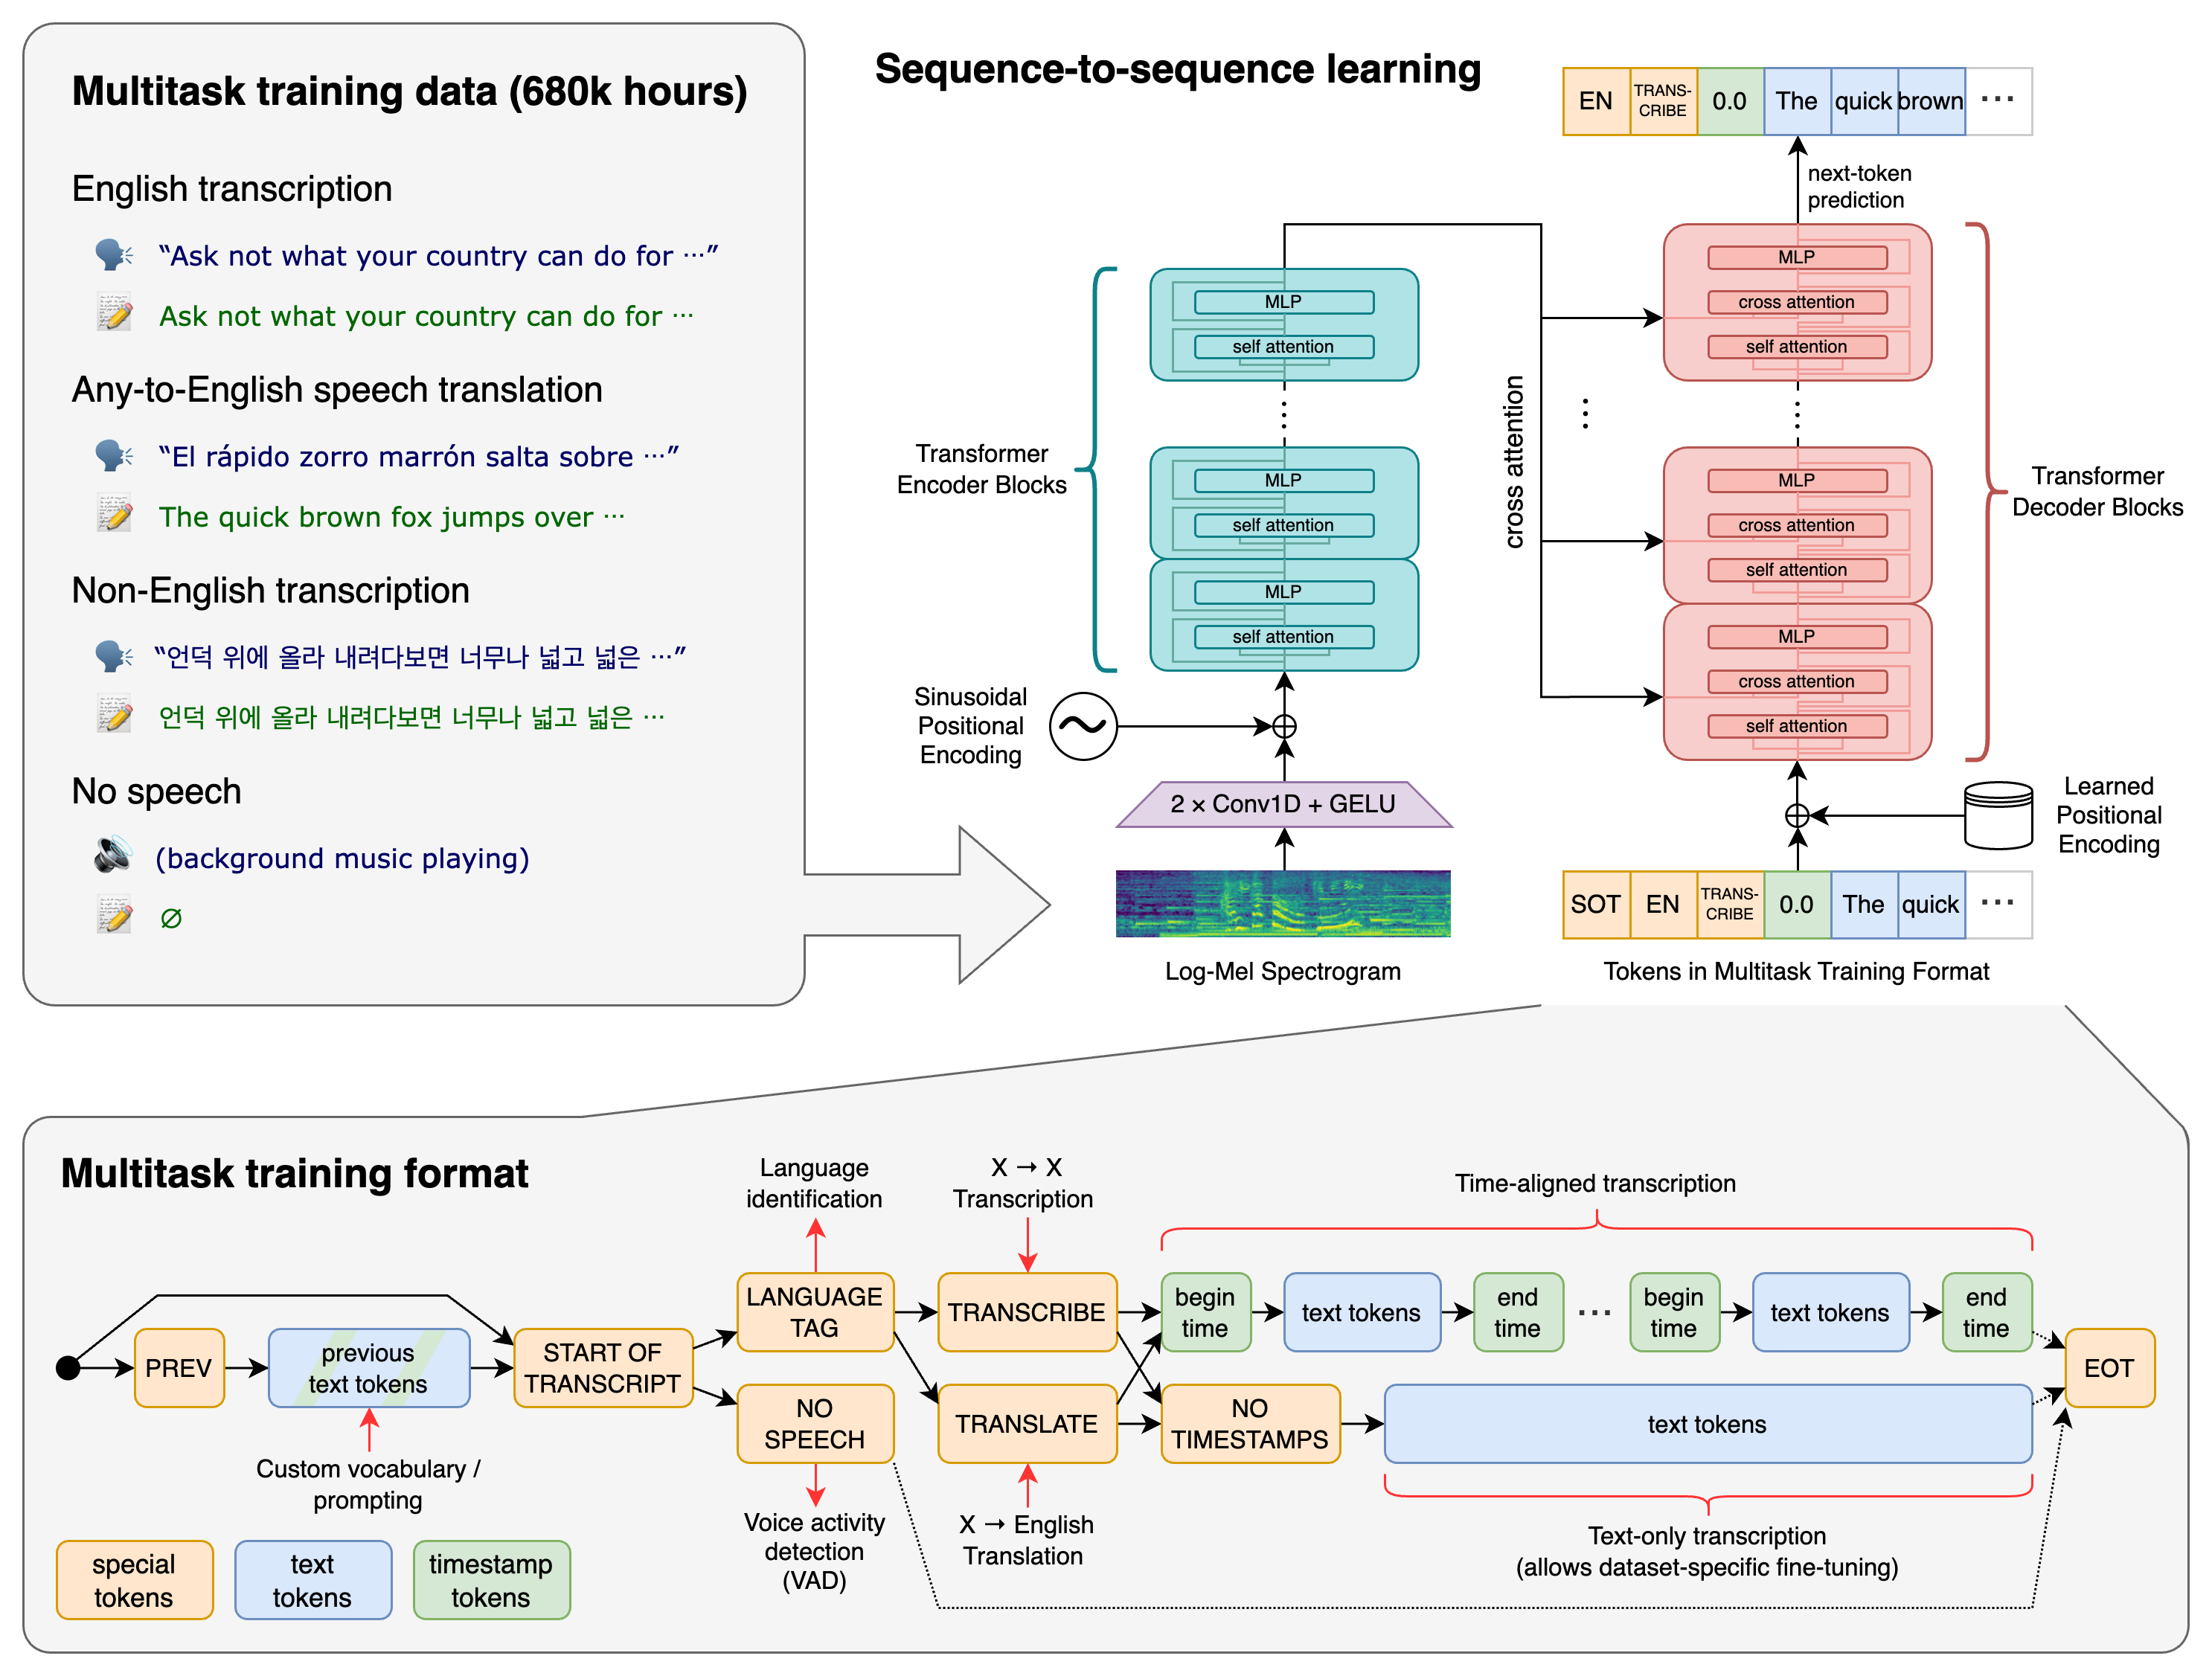 + +模型采用标准的 Transformer 序列到序列(sequence-to-sequence)架构,并在多种语音处理任务上联合训练,涵盖多语言语音识别、语音翻译、口语语种识别以及语音活动检测(VAD)。这些任务在解码端被统一表征为待预测的 Token 序列,从而让单个模型即可替代传统语音处理流程中的多个复杂阶段。多任务训练格式使用了一组特殊 Token(Special Tokens),作为任务指示符或分类目标。 + + +## 环境配置与安装 (Setup) + +我们使用 Python 3.9.9 和 [PyTorch](https://pytorch.org/) 1.10.1 训练并测试了模型,但该代码库预计可兼容 Python 3.8-3.11 以及最新的 PyTorch 版本。代码库还依赖若干 Python 包,尤其是 [OpenAI 的 tiktoken](https://github.com/openai/tiktoken) 提供的快速分词器实现。您可以通过以下命令下载并安装(或更新至)Whisper 的最新发布版本: + + pip install -U openai-whisper + +或者,您也可以运行以下命令直接拉取并安装本仓库的最新 Commit 及其 Python 依赖: + + pip install git+https://github.com/openai/whisper.git + +如需将软件包更新至本仓库的最新版本,请运行: + + pip install --upgrade --no-deps --force-reinstall git+https://github.com/openai/whisper.git + +此外,系统还需要安装命令行工具 [`ffmpeg`](https://ffmpeg.org/),大多数包管理器均可直接安装: + +```bash +# Ubuntu 或 Debian +sudo apt update && sudo apt install ffmpeg + +# Arch Linux +sudo pacman -S ffmpeg + +# MacOS(通过 Homebrew https://brew.sh/) +brew install ffmpeg + +# Windows(通过 Chocolatey https://chocolatey.org/) +choco install ffmpeg + +# Windows(通过 Scoop https://scoop.sh/) +scoop install ffmpeg +``` + +若 [tiktoken](https://github.com/openai/tiktoken) 未针对您的操作系统平台提供预构建的 wheel 包,您可能还需要安装 [`rust`](http://rust-lang.org)。若在执行上述 `pip install` 命令时遇到安装错误,请按照 [Rust 入门指南](https://www.rust-lang.org/learn/get-started) 安装 Rust 开发环境。此外,您可能需要配置 `PATH` 环境变量,例如 `export PATH="$HOME/.cargo/bin:$PATH"`。若安装报错提示 `No module named 'setuptools_rust'`,则需要手动安装 `setuptools_rust`,例如运行: + +```bash +pip install setuptools-rust +``` + + +## 支持的模型与语种 (Available models and languages) + +Whisper 提供六种模型尺寸,其中四种拥有纯英文专用版本,供用户在推理速度与识别精度之间进行权衡。 +下表列出了可用模型的名称、近似显存需求以及相对于 `large` 模型的推理速度。 +下表中的相对速度是在 A100 GPU 上转录英语语音时测得的,在实际应用中,实际速度可能会因语种、语速以及具体运行硬件等诸多因素而有明显差异。 + +| 模型尺寸 (Size) | 参数量 (Parameters) | 纯英文模型 (English-only) | 多语言模型 (Multilingual) | 所需显存 (VRAM) | 相对速度 (Relative speed) | +|:--------------:|:------------------:|:------------------------:|:-----------------------:|:--------------:|:------------------------:| +| tiny | 39 M | `tiny.en` | `tiny` | ~1 GB | ~10x | +| base | 74 M | `base.en` | `base` | ~1 GB | ~7x | +| small | 244 M | `small.en` | `small` | ~2 GB | ~4x | +| medium | 769 M | `medium.en` | `medium` | ~5 GB | ~2x | +| large | 1550 M | N/A | `large` | ~10 GB | 1x | +| turbo | 809 M | N/A | `turbo` | ~6 GB | ~8x | + +针对纯英语应用,带 `.en` 后缀的专属模型通常表现更佳,尤其是 `tiny.en` 与 `base.en` 模型。我们观察到,对于 `small.en` 与 `medium.en` 模型,这种性能差异会变得不那么显著。 +此外,`turbo` 模型是基于 `large-v3` 深度优化的版本,在几乎不损失识别精度的前提下提供了显著更快的转录速度。 + +Whisper 的性能表现因语种不同而有较大差异。下图展示了基于 Common Voice 15 和 Fleurs 数据集评估的 `large-v3` 和 `large-v2` 模型按语种细分的性能指标,分别采用字词错误率(WER)或字符错误率(CER,以*斜体*表示)。更多模型与数据集的 WER/CER 指标详见[原论文](https://arxiv.org/abs/2212.04356)附录 D.1、D.2 和 D.4,翻译任务的 BLEU 分数详见附录 D.3。 + + + +## 命令行使用指南 (Command-line usage) + +以下命令将使用 `turbo` 模型转录音频文件中的语音: + +```bash +whisper audio.flac audio.mp3 audio.wav --model turbo +``` + +默认设置(自动选用 `turbo` 模型)在转录英语时效果极佳。然而,**`turbo` 模型未针对翻译任务进行训练**。如果您需要**将非英语语音翻译为英语文本**,请选用**多语言模型**(`tiny`、`base`、`small`、`medium`、`large`),而不是 `turbo`。 + +例如,若要转录包含非英语语音的音频文件,您可以指定目标语种: + +```bash +whisper japanese.wav --language Japanese +``` + +若要将语音**翻译**为英语,请使用: + +```bash +whisper japanese.wav --model medium --language Japanese --task translate +``` + +> **注意:** 即使指定了 `--task translate`,`turbo` 模型仍会返回原语种文本。如需获得最佳翻译效果,请使用 `medium` 或 `large` 模型。 + +运行以下命令可查看所有支持的命令行参数选项: + +```bash +whisper --help +``` + +所有支持的完整语种列表请参阅 [tokenizer.py](https://github.com/openai/whisper/blob/main/whisper/tokenizer.py)。 + + +## Python 编程接口 (Python usage) + +在 Python 代码中同样可以便捷地执行语音转录: + +```python +import whisper + +model = whisper.load_model("turbo") +result = model.transcribe("audio.mp3") +print(result["text"]) +``` + +在底层实现中,`transcribe()` 方法会读取完整音频文件,并采用 30 秒滑动窗口切分处理音频,对每个时间窗口执行自回归(autoregressive)序列到序列预测。 + +以下示例演示了如何使用 `whisper.detect_language()` 和 `whisper.decode()`,这两个接口提供了对模型的更底层访问控制: + +```python +import whisper + +model = whisper.load_model("turbo") + +# 加载音频并填充/截断至标准的 30 秒长度 +audio = whisper.load_audio("audio.mp3") +audio = whisper.pad_or_trim(audio) + +# 计算 Log-Mel 声学梅尔频谱图,并移动到与模型相同的计算设备上 +mel = whisper.log_mel_spectrogram(audio, n_mels=model.dims.n_mels).to(model.device) + +# 检测音频所使用的语种 +_, probs = model.detect_language(mel) +print(f"检测到的语种: {max(probs, key=probs.get)}") + +# 对音频执行解码 +options = whisper.DecodingOptions() +result = whisper.decode(model, mel, options) + +# 打印识别出的文本内容 +print(result.text) +``` + +## 更多示例 (More examples) + +欢迎访问 GitHub Discussions 中的 [🙌 Show and tell](https://github.com/openai/whisper/discussions/categories/show-and-tell) 交流板块,分享更多 Whisper 的实战用例以及第三方扩展工具(例如 Web 演示应用、与其他工具的集成套件、跨平台移植方案等)。 + + +## 开源许可证 (License) + +Whisper 的代码与模型权重均在 MIT License 下开源发布。详情请参阅 [LICENSE](https://github.com/openai/whisper/blob/main/LICENSE)。 + +--- + +> 💡 **文档维护说明**:本中文文档由社区志愿者(@JasonYeYuhe)翻译维护,最后同步更新于 2026年10月15日。如发现内容与官方英文原版存在差异或新特性滞后,欢迎提交 PR 共同完善!